SNWN Tech Solution delivers enterprise Generative AI services, transforming experimental AI models into secure, scalable, production-ready solutions. We develop custom RAG pipelines, fine-tuned foundation models, autonomous AI agents, and robust security guardrails to protect sensitive data, strengthen compliance, automate workflows, optimize operational efficiency, and maximize measurable business ROI.
Engineered for enterprise reliability, high-throughput model performance, and absolute compliance.
Optimized GPU inference engines using TensorRT-LLM and vLLM, combined with semantic prompt caching and quantized model serving for real-time applications.
Hybrid dense-sparse semantic vector search, knowledge graph grounding, cross-encoder reranking, and automated citation validation guardrails.
Private Virtual Private Cloud (VPC) deployments, Customer-Managed Encryption Keys (CMEK), Zero-Data-Retention (ZDR) SLAs, and fully air-gapped LLM hosting options.
Intelligent dynamic model routing, semantic response caching, small language model (SLM) distillation, and speculative decoding optimizations.
Exposing proprietary IP and customer PII to public model endpoints without auditable access boundaries.
Sovereign Enclaves: Isolated VPC deployment with Customer-Managed Keys (CMEK), real-time PII masking, and role-based access controls.
Models generating false or unverified facts, eroding operational reliability and compliance trust.
Agentic RAG Pipelines: Multi-stage contextual reranking, dense-sparse hybrid search, knowledge graph validation, and real-time citation links.
Directing all queries to frontier LLMs, leading to unpredictable token costs at scale.
Model Cascading: Dynamic query routing using distilled SLMs for routine processing, escalating to frontier models only for complex reasoning.
Multi-second token response latency creating bottlenecks in interactive user workflows.
Hardware Acceleration: TensorRT-LLM and vLLM execution, KV-cache sharing, continuous batching, and edge streaming.
Susceptibility to prompt injection attacks, lack of audit trails, and non-compliance with global standards.
NeMo Guardrails & Firewalls: Input/output sanitization, strict boundary policy enforcement, and comprehensive forensic logging.
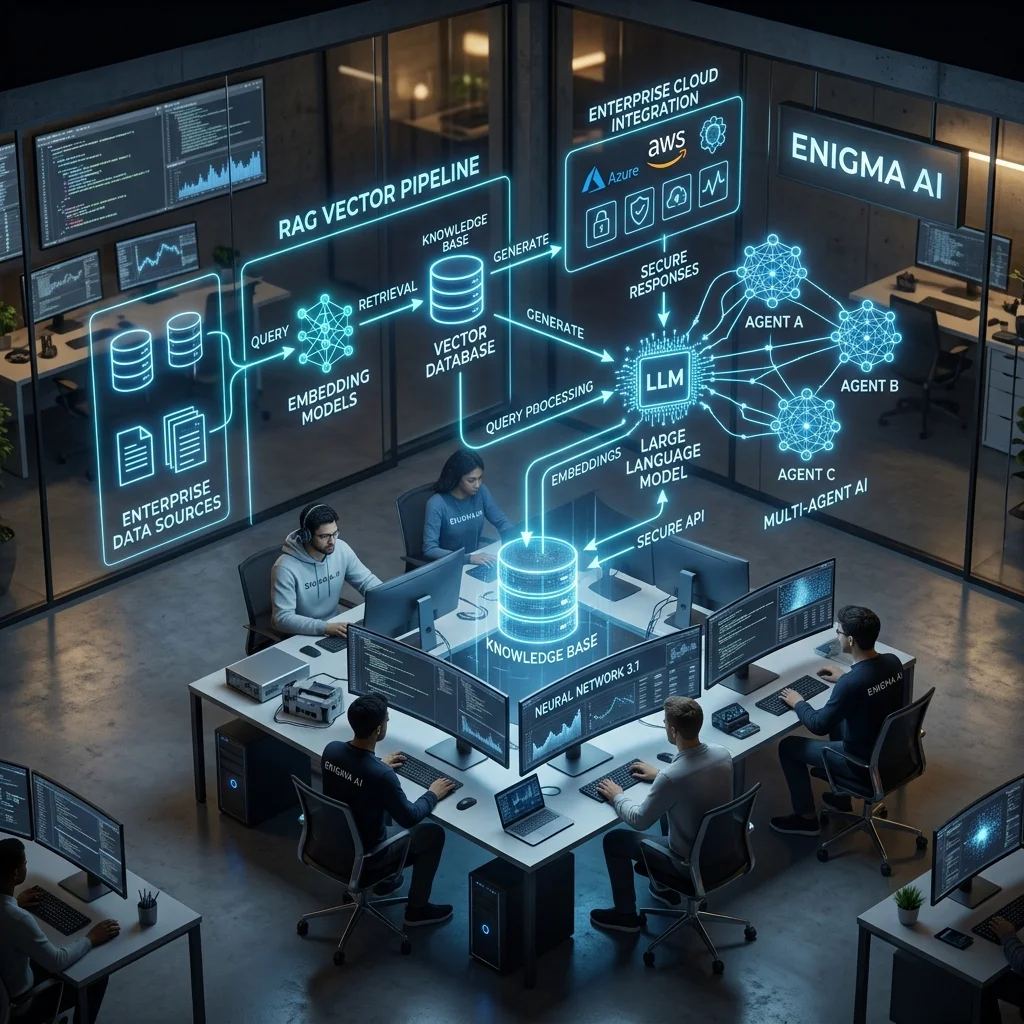
Transform static enterprise databases into high-precision context streams using hybrid vector search, knowledge graphs, and multi-stage semantic reranking.
Orchestrate stateful multi-agent workflows built on LangGraph and CrewAI with audited enterprise ERP tool-calling and human-in-the-loop oversight guardrails.
Fine-tune open-weights Llama, Mistral, and Gemma foundation models using PEFT LoRA and 4-bit quantization for domain-specific enterprise mastery.
Embed real-time NeMo Guardrails, prompt injection defenses, PII redaction, and EU AI Act compliance telemetry across inference pipelines.
Quality Management System
Information Security Management
Azure Solutions Architect
Solutions Architect & CloudOps
RHCE Linux Enterprise
Certified Systems Professional
Certified Administrator
Software Testing & Automation
Quality Management System
Information Security Management
Azure Solutions Architect
Solutions Architect & CloudOps
RHCE Linux Enterprise
Certified Systems Professional
Certified Administrator
Software Testing & Automation
Evaluating high-impact workflows, data hygiene, compliance boundaries, and return on investment targets.
Building context ingestion pipelines, vector index topologies, prompt strategies, and base safety guardrails.
Executing domain fine-tuning, prompt compression, and quantization benchmarking to hit target latency SLAs.
Connecting agents to internal ERP/CRM systems with SSO/RBAC controls and running automated red-teaming tests.
Deploying continuous monitoring for hallucination drift, token consumption, query latency, and user sentiment.
We deploy self-hosted models directly inside your isolated virtual private cloud (AWS, Azure, GCP) or leverage commercial enterprise API agreements backed by strict Zero-Data-Retention (ZDR) guarantees. Data remains entirely within your sovereign perimeter.
RAG provides dynamic access to live enterprise content without retraining, guaranteeing up-to-date factual citations. Fine-tuning modifies internal model weights to adapt tone, format, and domain syntax. In enterprise settings, we combine RAG for factual knowledge with fine-tuning for domain precision.
Schedule a strategic technical deep-dive with an AI Principal Architect at SNWN Tech Solution to review your enterprise use cases and construct a high-throughput, secure deployment roadmap.